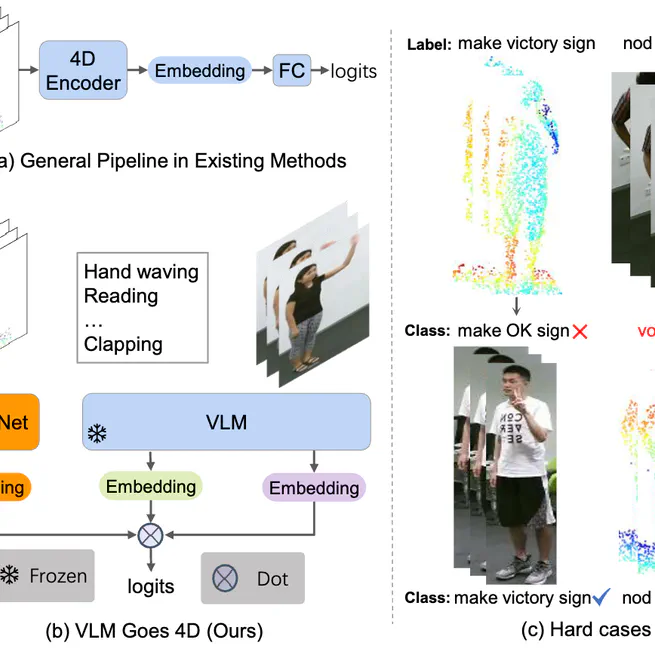
VG4D: Vision-Language Model Goes 4D Video Recognition
A Vision-Language Model Goes 4D (VG4D) framework that transfers VLM knowledge to 4D point cloud networks for improved video recognition, achieving state-of-the-art performance on action recognition datasets.
May 13, 2024
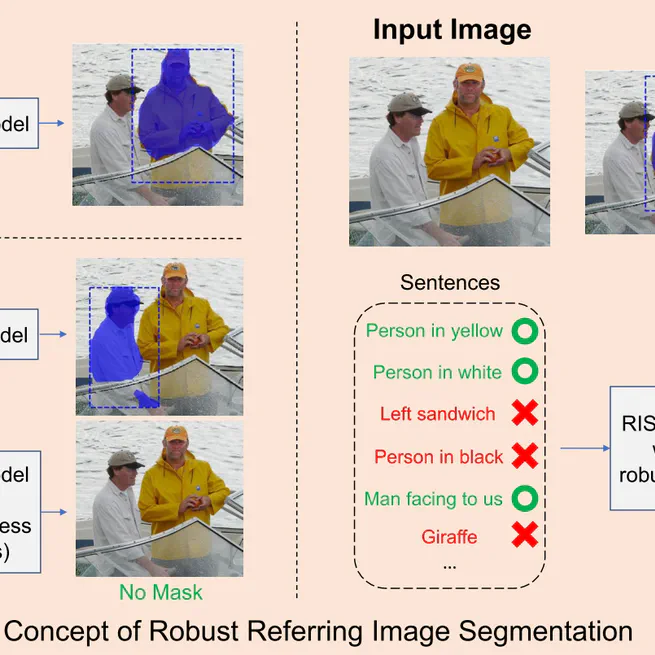
Towards robust referring image segmentation
We propose a novel ranking loss function, named Bi-directional Exponential Angular Triplet Loss, to help learn an angularly separable common feature space by explicitly constraining the included angles between embedding vectors.
Mar 5, 2024
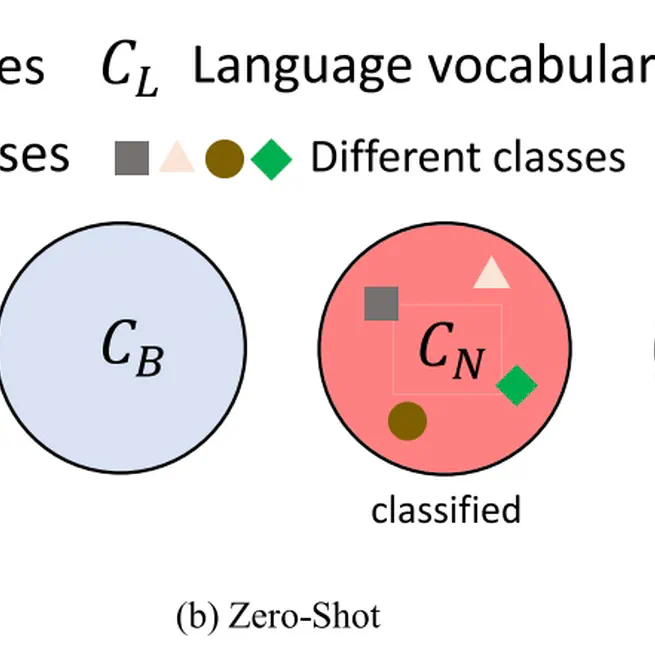
Towards open vocabulary learning: A survey
This survey offers a detailed examination of the latest developments in open vocabulary learning in computer vision, which appears to be a first of its kind. We provide an overview of the necessary background knowledge, which includes fundamental concepts and introductory knowledge of detection, segmentation, and vision language pre-training. Following that, we summarize more than 50 different models used for various scene understanding tasks. For each task, we categorize the methods based on their technical viewpoint. Additionally, we provide information regarding several closely related domains. In the experiment section, we provide a detailed description of the settings and compare results fairly. Finally, we summarize several challenges and also point out several future research directions for open vocabulary learning.
Feb 5, 2024
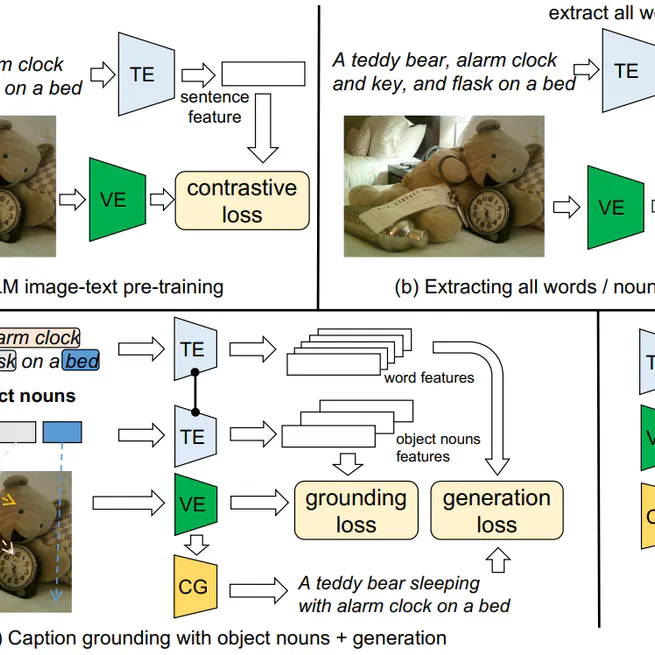
Betrayed by captions: Joint caption grounding and generation for open vocabulary instance segmentation
This paper presents a joint Caption Grounding and Generation (CGG) framework for instance-level open vocabulary segmentation. The main contributions are: (1) using fine-grained object nouns in captions to improve grounding with object queries. (2) using captions as supervision signals to extract rich information from other words helps identify novel categories. To our knowledge, this paper is the first to unify segmentation and caption generation for open vocabulary learning. The proposed framework significantly improves OVIS and OSPS and comparable results on OVOD without pre-training on large-scale datasets.
Oct 2, 2023
Towards efficient scene understanding via squeeze reasoning
Jul 30, 2021
PointFlow: Flowing Semantics Through Points for Aerial Image Segmentation
Feb 13, 2021
Improving Semantic Segmentation via Decoupled Body and Edge Supervision
Jul 3, 2020